Product introduction
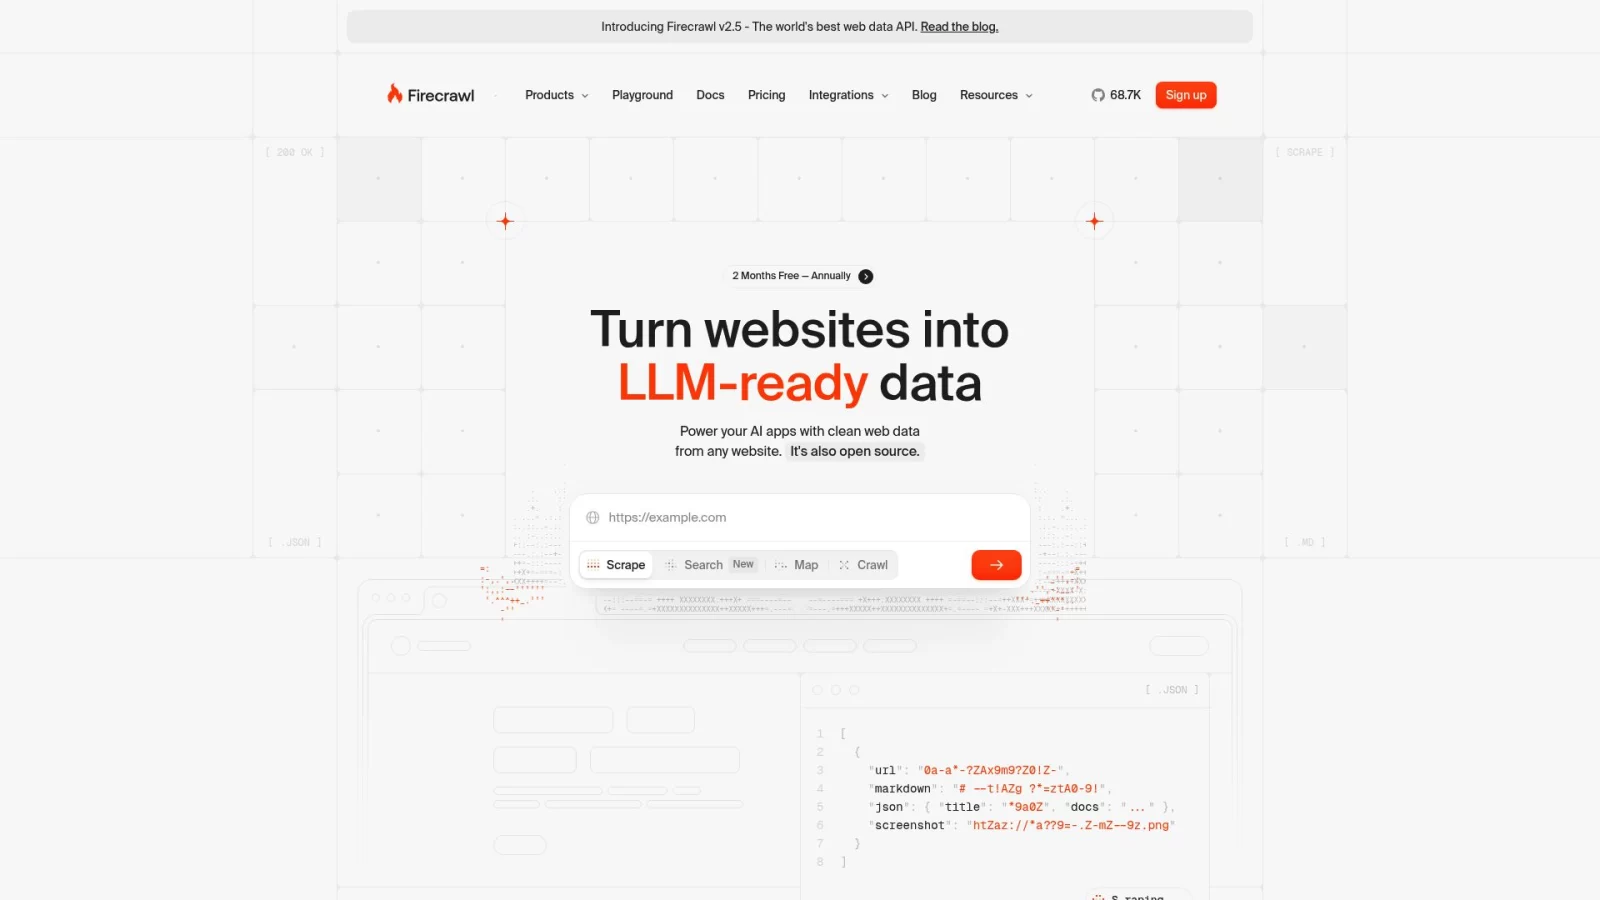
Firecrawl is an efficient web data extraction service designed for large language models (LLMs), dedicated to transforming complex internet content into structured, easily processable formats. It automatically traverses and scrapes all accessible pages of a website without relying on traditional sitemaps, standardizing results into AI-friendly formats like Markdown, JSON, or HTML. With powerful anti-bot bypass capabilities and dynamic content processing mechanisms, Firecrawl operates stably under high concurrency, ensuring data real-time availability and integrity.
The tool supports not only basic text and image extraction but also allows developers to finely control crawling behavior through custom rules, such as limiting depth or filtering specific tags. Whether building RAG applications, conducting market research, or automating data collection, Firecrawl provides a reliable data pipeline, helping enterprises and developers easily convert unstructured web pages into usable information.
Key Features
- Intelligent Single-Page Scraping: Performs deep parsing of specified URLs, outputting multiple formats including Markdown, summaries, screenshots, and structured JSON to adapt to the input needs of different AI models.
- Full-Site Automatic Crawling: Automatically discovers and traverses all sub-links within the target site, batch-generating LLM-compatible content formats, eliminating the tedious process of manually configuring each page URL.
- Sitemap Mapping: Quickly scans and generates a complete list of site URLs, intuitively displaying the website structure to provide foundational data support for SEO analysis and content auditing.
- Web Search Integration: Directly executes web search commands and retrieves full content from search result pages, expanding the data source boundaries for AI applications and enabling broader information integration.
- AI Structured Extraction: Uses artificial intelligence technology to precisely extract specific fields from single or multiple pages, supporting custom data schemas and significantly reducing the difficulty of extracting key information from unstructured text.
Use Cases
- AI Model Training & Enhancement: Provides high-quality, cleaned web corpus for RAG systems or large models, improving the accuracy of knowledge retrieval and the reliability of model responses.
- B2B Lead Generation: Automates the collection of public information from industry directories and corporate websites, extracting contact details and business profiles to help sales teams efficiently expand their potential customer base.
- SEO Competitive Intelligence Analysis: Monitors competitors' website page structures, keyword layouts, and update frequencies, providing data basis for SEO strategies to improve website traffic performance.
- Academic & Industry Research: Mass-scrapes academic papers, research reports, and news materials, accelerating literature reviews and information summarization processes to empower scientific research and innovation decisions.